Evaluation-driven LLM application development to systematically improve applications
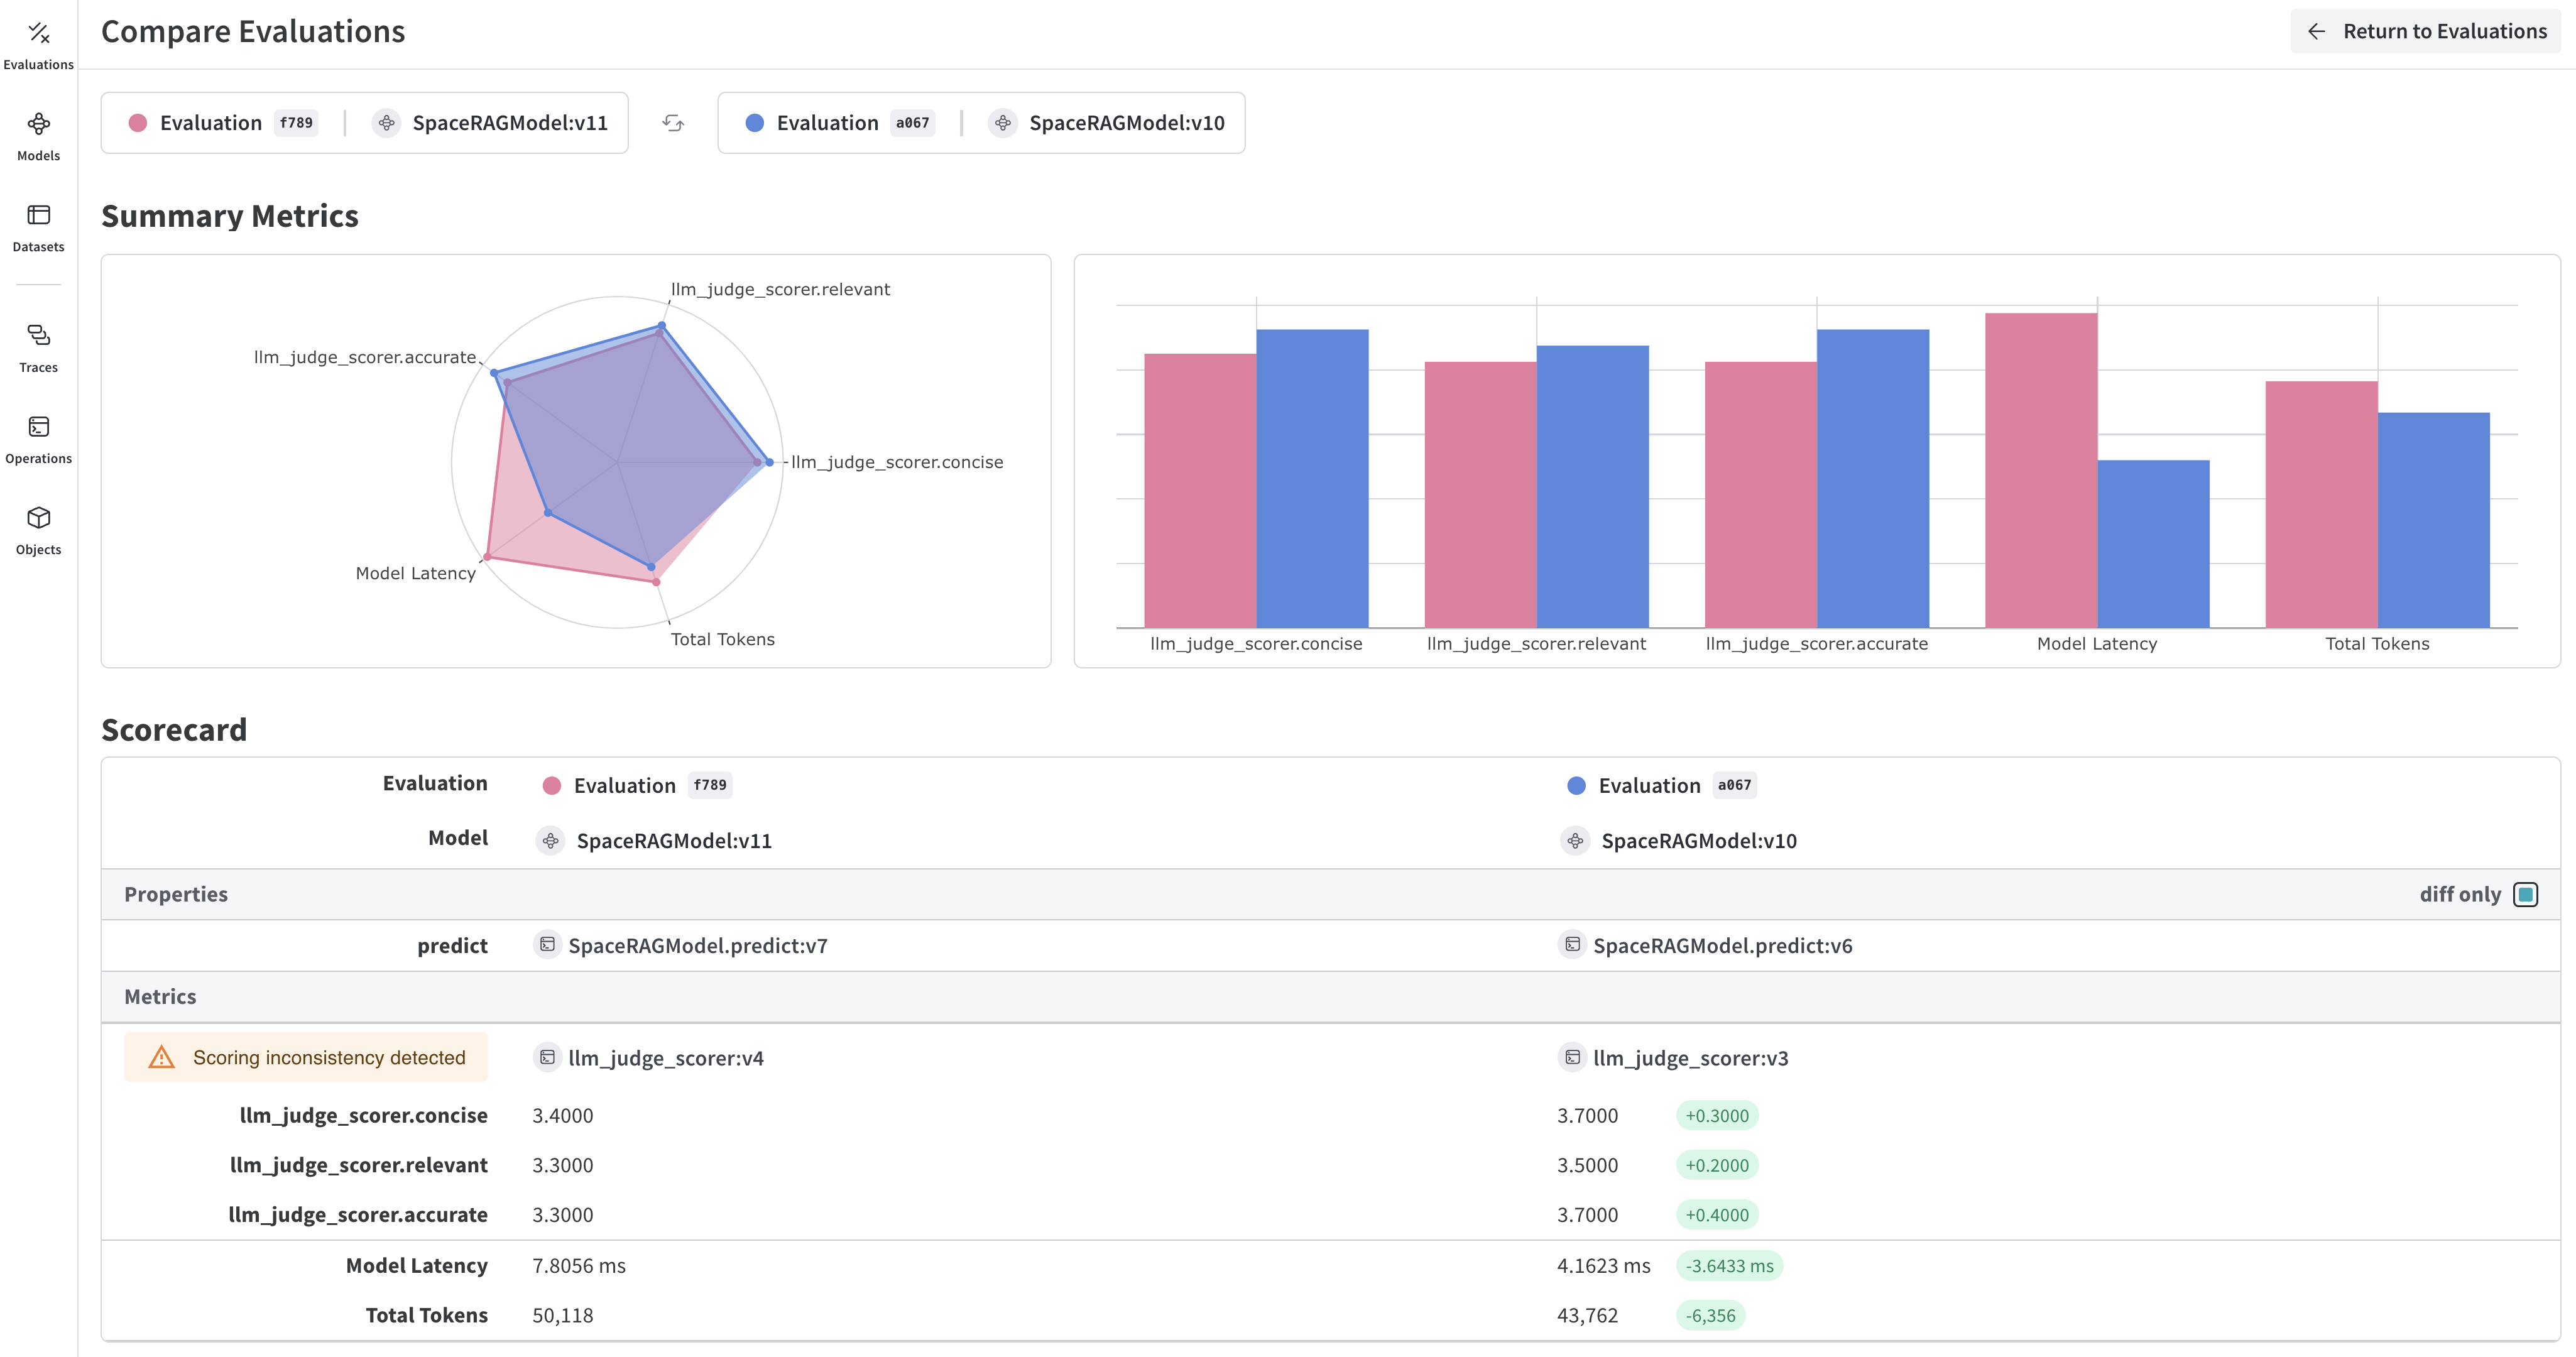
Evaluation-driven LLM application development helps you systematically improve LLM applications by systematically measuring their behavior using consistent, curated examples.In Weave, the core of the workflow is the Evaluation object, which defines:
A Dataset or list of dictionaries for test examples.
Once you’ve defined the Evaluation, you can run it against a Model object or any custom function containing LLM application logic. Each call to .evaluate() triggers an evaluation run. Think of the Evaluation object as a blueprint, and each run as a measurement of how your application performs under that setup.To get started with evaluations, complete the following steps:
Creating an Evaluation object is the first step in setting up your evaluation configuration. An Evaluation consists of example data, scoring logic, and optional preprocessing. You’ll later use it to run one or more evaluations.Weave will take each example, pass it through your application and score the output on multiple custom scoring functions. By doing this, you’ll have a view of the performance of your application, and a rich UI to drill into individual outputs and scores.
To name the Evaluation object itself, pass an evaluation_name parameter to the Evaluation class. This name helps you identify the Evaluation in code and UI listings.
To name a specific evaluation run (a call to evaluate()), use the __weave dictionary with a display_name. This affects what is shown in the UI for that run.
evaluation = Evaluation( dataset=examples, scorers=[match_score1])evaluation.evaluate(model, __weave={"display_name": "My Evaluation Run"})
First, define a Dataset object or list of dictionaries with a collection of examples to be evaluated. These examples are often failure cases that you want to test for, these are similar to unit tests in Test-Driven Development (TDD).The following examples shows a dataset defined as a list of dictionaries:
examples = [ {"question": "What is the capital of France?", "expected": "Paris"}, {"question": "Who wrote 'To Kill a Mockingbird'?", "expected": "Harper Lee"}, {"question": "What is the square root of 64?", "expected": "8"},]
Then, create one or more scoring functions. These are used to score each example in the Dataset. Each scoring function must have a output, and return a dictionary with the scores. Optionally, you can include other inputs from your examples.Scoring functions need to have a output keyword argument, but the other arguments are user defined and are taken from the dataset examples. It will only take the necessary keys by using a dictionary key based on the argument name.
If your scorer expects an output argument but isn’t receiving it, check if it might be using the legacy model_output key. To fix this, update your scorer function to use output as a keyword argument.
The following example scorer function match_score1 uses the expected value from the examples dictionary for scoring.
import weave# Collect your examplesexamples = [ {"question": "What is the capital of France?", "expected": "Paris"}, {"question": "Who wrote 'To Kill a Mockingbird'?", "expected": "Harper Lee"}, {"question": "What is the square root of 64?", "expected": "8"},]# Define any custom scoring function@weave.op()def match_score1(expected: str, output: dict) -> dict: # Here is where you'd define the logic to score the model output return {'match': expected == output['generated_text']}
In some applications we want to create custom Scorer classes - where for example a standardized LLMJudge class should be created with specific parameters (e.g. chat model, prompt), specific scoring of each row, and specific calculation of an aggregate score.See the tutorial on defining a Scorer class in Model-Based Evaluation of RAG applications for more information.
To evaluate a Model, call evaluate on it using an Evaluation. Models are used when you have parameters that you want to experiment with and capture in weave.
from weave import Model, Evaluationimport asyncioclass MyModel(Model): prompt: str @weave.op() def predict(self, question: str): # here's where you would add your LLM call and return the output return {'generated_text': 'Hello, ' + self.prompt}model = MyModel(prompt='World')evaluation = Evaluation( dataset=examples, scorers=[match_score1])weave.init('intro-example') # begin tracking results with weaveasyncio.run(evaluation.evaluate(model))
This will run predict on each example and score the output with each scoring functions.
Alternatively, you can also evaluate a custom function tracked by @weave.op().
@weave.opdef function_to_evaluate(question: str): # here's where you would add your LLM call and return the output return {'generated_text': 'some response'}asyncio.run(evaluation.evaluate(function_to_evaluate))
To run an evaluation, call .evaluate() on the object you want to evaluate.
For example, assuming an Evaluation object called evaluation and a Model object to evaluate called model, the following code instatiates an evaluation run.
asyncio.run(evaluation.evaluate(model))
Evaluation run tips
The evaluate() method returns a summary of results across all examples. To access the full set of scored rows including outputs and scores, use get_eval_results().
If you don’t provide a display_name when calling .evaluate(), Weave will automatically generate one using the date and a random memorable name. To learn more, see how to name individual evaluation runs.
The model passed to .evaluate must be a Model or a function tracked with @weave.op. Regular Python functions are not supported unless wrapped with @weave.op.
The following code sample demonstrates a complete evaluation run from start to finish. The examples dictionary is used by the match_score1 and match_score2 scoring functions to evaluate MyModel given the value of prompt, as well as a custom function function_to_evaluate. The evaluation runs for both the Model and the function are invoked via asyncio.run(evaluation.evaluate().
from weave import Evaluation, Modelimport weaveimport asyncioweave.init('intro-example')examples = [ {"question": "What is the capital of France?", "expected": "Paris"}, {"question": "Who wrote 'To Kill a Mockingbird'?", "expected": "Harper Lee"}, {"question": "What is the square root of 64?", "expected": "8"},]@weave.op()def match_score1(expected: str, output: dict) -> dict: return {'match': expected == output['generated_text']}@weave.op()def match_score2(expected: dict, output: dict) -> dict: return {'match': expected == output['generated_text']}class MyModel(Model): prompt: str @weave.op() def predict(self, question: str): # here's where you would add your LLM call and return the output return {'generated_text': 'Hello, ' + question + self.prompt}model = MyModel(prompt='World')evaluation = Evaluation(dataset=examples, scorers=[match_score1, match_score2])asyncio.run(evaluation.evaluate(model))@weave.op()def function_to_evaluate(question: str): # here's where you would add your LLM call and return the output return {'generated_text': 'some response' + question}asyncio.run(evaluation.evaluate(function_to_evaluate("What is the capitol of France?")))
The preprocess_model_input function is only applied to inputs before passing them to the model’s prediction function. Scorer functions always receive the original dataset example, without any preprocessing applied.
The preprocess_model_input parameter allows you to transform your dataset examples before they are passed to your evaluation function. This is useful when you need to:
Rename fields to match your model’s expected input
Transform data into the correct format
Add or remove fields
Load additional data for each example
Here’s a simple example that shows how to use preprocess_model_input to rename fields:
import weavefrom weave import Evaluationimport asyncio# Our dataset has "input_text" but our model expects "question"examples = [ {"input_text": "What is the capital of France?", "expected": "Paris"}, {"input_text": "Who wrote 'To Kill a Mockingbird'?", "expected": "Harper Lee"}, {"input_text": "What is the square root of 64?", "expected": "8"},]@weave.op()def preprocess_example(example): # Rename input_text to question return { "question": example["input_text"] }@weave.op()def match_score(expected: str, output: dict) -> dict: return {'match': expected == output['generated_text']}@weave.op()def function_to_evaluate(question: str): return {'generated_text': f'Answer to: {question}'}# Create evaluation with preprocessingevaluation = Evaluation( dataset=examples, scorers=[match_score], preprocess_model_input=preprocess_example)# Run the evaluationweave.init('preprocessing-example')asyncio.run(evaluation.evaluate(function_to_evaluate))
In this example, our dataset contains examples with an input_text field, but our evaluation function expects a question parameter. The preprocess_example function transforms each example by renaming the field, allowing the evaluation to work correctly.The preprocessing function:
Receives the raw example from your dataset
Returns a dictionary with the fields your model expects
Is applied to each example before it’s passed to your evaluation function
This is particularly useful when working with external datasets that may have different field names or structures than what your model expects.
We are continuously improving our integrations with third-party services and libraries.While we work on building more seamless integrations, you can use preprocess_model_input as a temporary workaround for using HuggingFace Datasets in Weave evaluations.See our Using HuggingFace datasets in evaluations cookbook for the current approach.
You can save your Evals table configurations, filters, and sorts as saved views for quick access to your preferred setup. You can configure and access saved views via the UI and the Python SDK. For more information, see Saved Views.
If you prefer a more flexible evaluation framework, check out Weave’s EvaluationLogger. The imperative approach offers more flexibility for complex workflows, while the standard evaluation framework provides more structure and guidance.
Was this page helpful?
Assistant
Responses are generated using AI and may contain mistakes.